AV2TEXTAV2TEXT
Drop in a recording and get a timestamped transcript in 30 seconds. Fully offline - the audio never leaves the machine.录音不用上传云端,30 秒出带时间戳的文字稿——完全离线,音频不出本机。
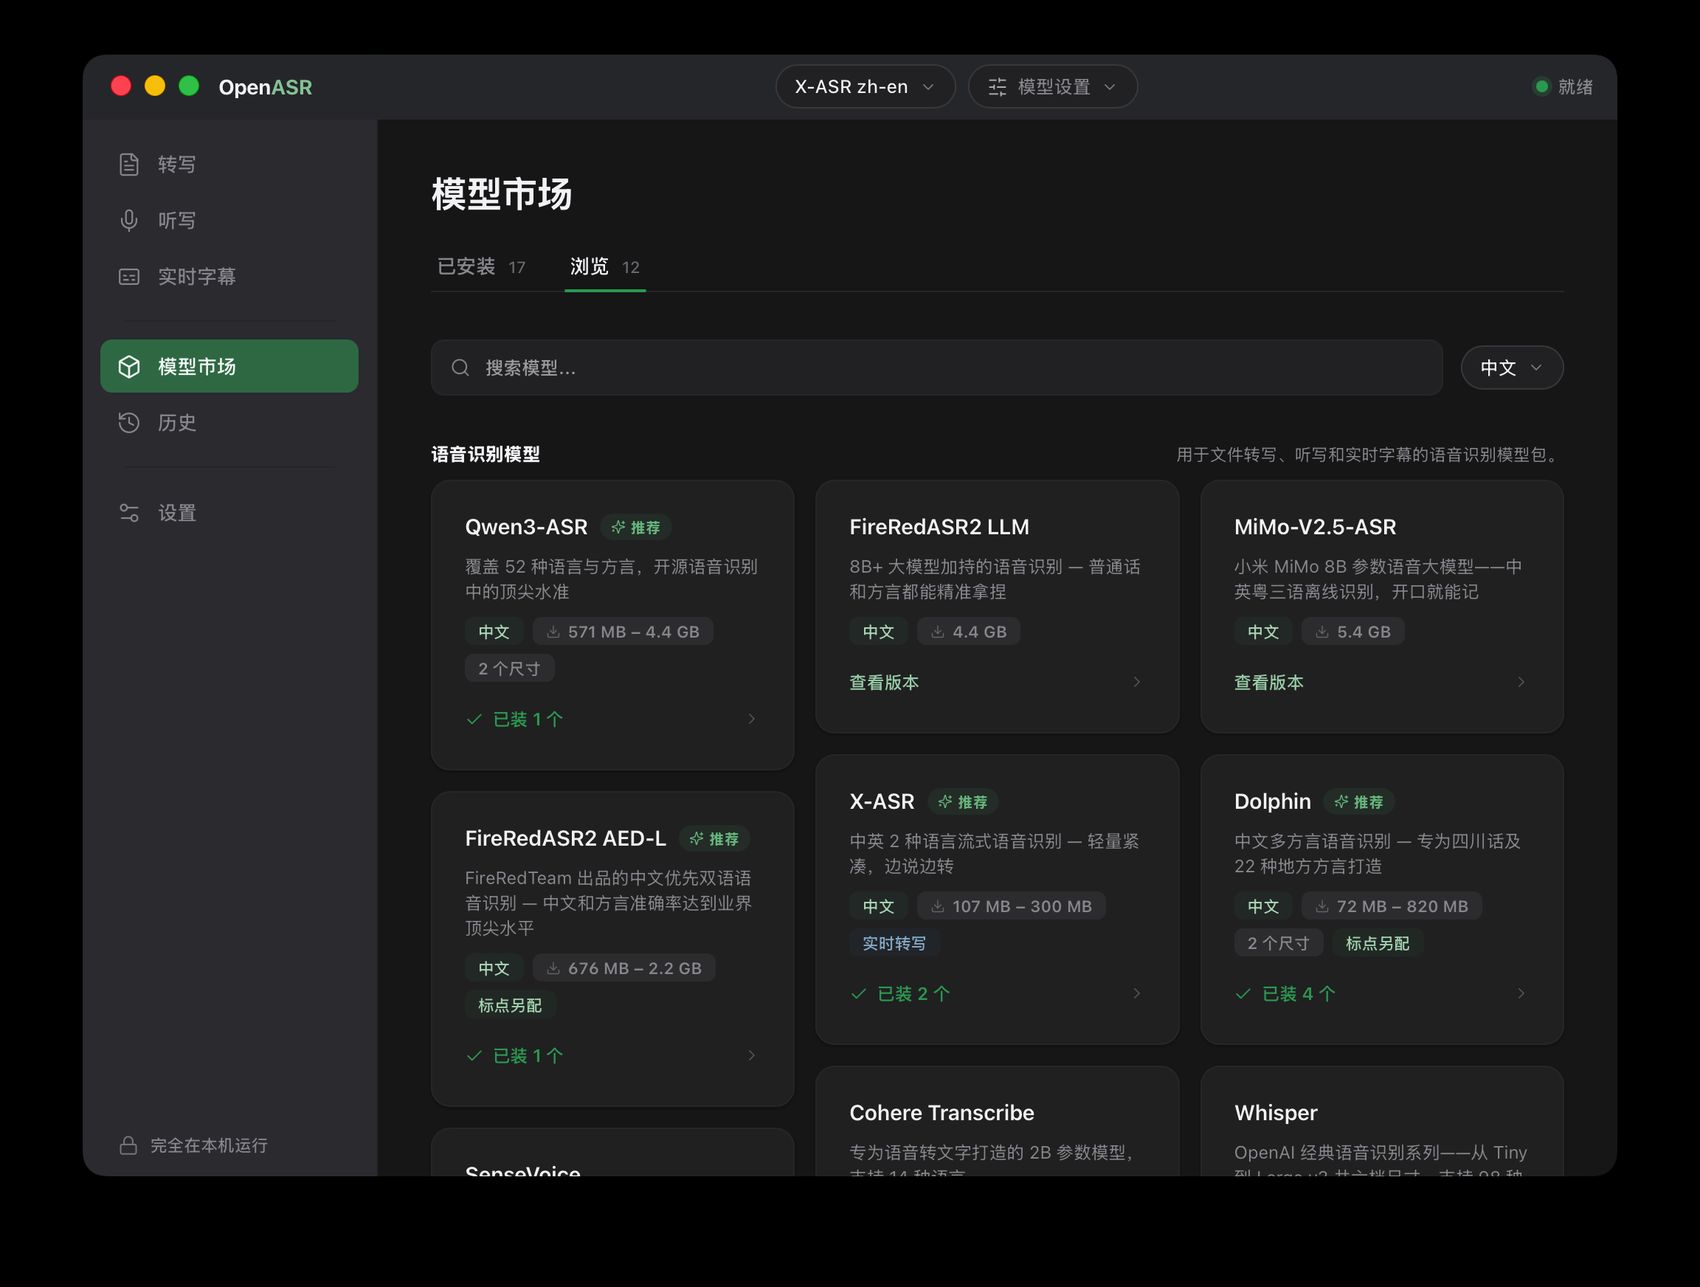
What it does做到了什么
- Partial results under 1 second on CPU, no GPU requiredCPU 实时推理,partial 延迟小于 1 秒,不需要显卡
- Paste a Bilibili or YouTube link and it pulls the audio track itself粘贴 B 站 / YouTube 链接即可自动取音轨转写
- Exports TXT / SRT / LRC / DOCX / PDF导出 TXT / SRT / LRC / DOCX / PDF
- Embedded Python engine with local TCP auth and SSRF guards嵌入式 Python 引擎,本地 TCP 鉴权 + SSRF 防护
- Models downloaded on demand from Aliyun OSS and Cloudflare R2模型按需从阿里云 OSS 与 Cloudflare R2 双 CDN 下载
Meetings, lectures and interviews are the most sensitive audio most people own, and the easy cloud tools all require uploading it. AV2TEXT runs the whole chain locally: decode, voice activity detection, ASR, punctuation, export.会议、讲座、访谈是大多数人手里最敏感的音频,而好用的云端工具都要求你先上传。AV2TEXT 把整条链路放在本机:解码、静音检测、识别、标点、导出。
Choosing the engine was most of the work选型占了这件事一半的工作量
Qwen3-ASR looked right until the ctypes binding for b10068 turned into an afternoon of crashes. The fallback - X-ASR-zh-en on sherpa-onnx with a Zipformer transducer - is smaller, runs realtime on CPU, and has been stable since.Qwen3-ASR 看起来最合适,直到 b10068 的 ctypes 绑定让我搭进去一个下午的崩溃排查。退回到 sherpa-onnx + Zipformer transducer 的 X-ASR-zh-en 之后:体积更小、CPU 就能实时跑,之后再没出过问题。
Shipping to machines you will never touch发给一台你永远碰不到的电脑
The packaging constraint changed the architecture: the engine and the models had to be bundled or fetched, Python could not be assumed, and the IPC between the Rust shell and the embedded interpreter needed its own auth so a local process could not drive the transcription engine.分发约束反过来决定了架构:引擎与模型要么内置要么按需下载,不能假设目标电脑装了 Python,Rust 外壳与内嵌解释器之间的 IPC 必须自带鉴权——否则本机任意进程都能驱动转写引擎。
- The earlier Python version (影音口录助手 2.1.0) is still the packaged installer for users on older machines更早的 Python 版(影音口录助手 2.1.0)仍作为老机器的安装包保留
- Model CDN is dual-provider so one blocked domain does not brick a fresh install模型走双 CDN,单一域名被墙不会让全新安装变成砖
- Full offline after the first model download首次下载模型之后可完全离线运行